Understand why an article is not indexed on Google and check out a step-by-step guide to diagnose and resolve organic visibility issues.
Written and published by Blog Post Automatic-O
An article does not appear on Google when the search engine failed to discover the URL, was blocked during crawling, or evaluated the page as insufficient for Google indexing. To fix the issue of an unindexed article, it is necessary to identify at which stage of the search flow the page was held back.
The difference between discovery, crawling, indexing, and ranking
The exact cause of an article not being displayed in search depends directly on the phase in which Google's crawler encountered an obstacle. Confusing these stages leads managers to apply the wrong fixes, such as rewriting an impeccable text that the bot didn't even visit.
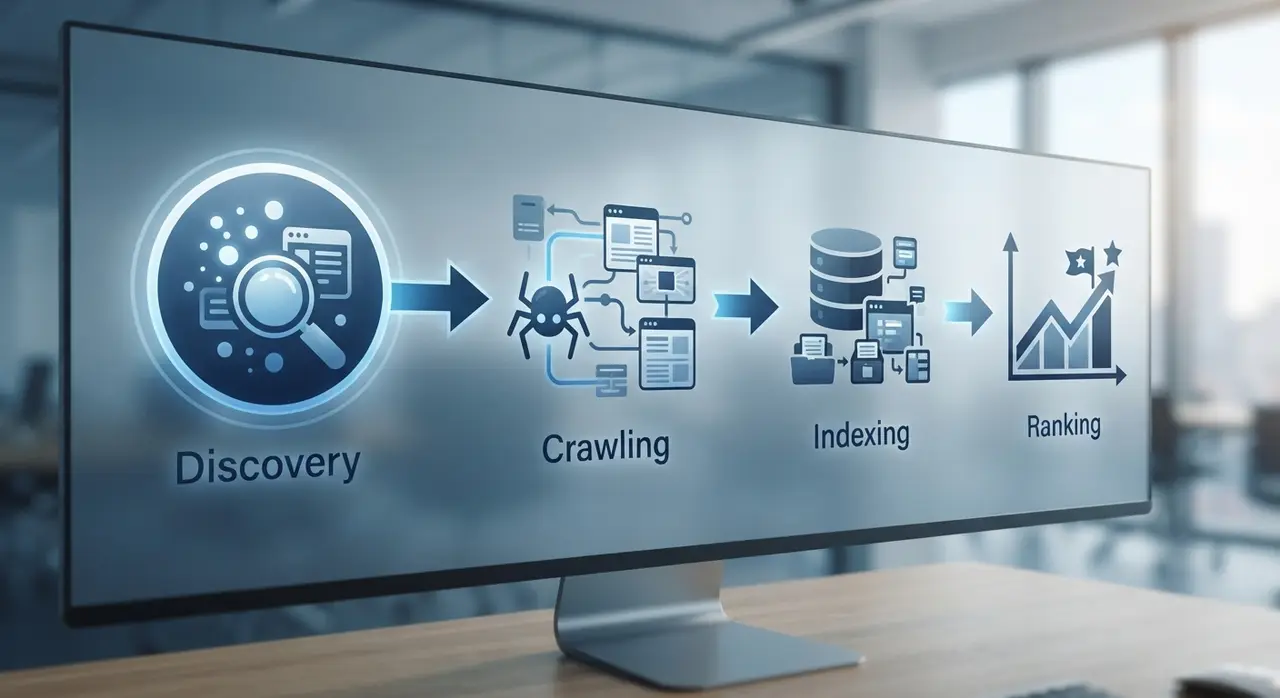
The search process occurs in four sequential steps:
- Discovery: Google discovers that the URL exists through XML sitemaps or links from other sites.
- Crawling: The bot (Googlebot) downloads the page's HTML code, images, and assets to read its content.
- Indexing: Google analyzes the quality, originality, and relevance of the content and decides whether to store it in its official database.
- Ranking: The algorithm positions the indexed page in the responses for specific user searches.
If your article does not appear in search, the problem lies in one of these four points. Understanding this distinction saves hours of technical and editorial rework.
Technical diagnosis: HTTP status, robots, and canonical tags
Technical configuration failures in robots or header tags can explicitly prohibit Google from storing a page. Before questioning the text quality, it is essential to audit it at the web infrastructure level.
The three primary technical block points are:
- Incorrect HTTP status code: If the server returns codes such as 404 (not found), 403 (forbidden), or 500 (internal error), the crawler will stop processing the URL.
- noindex directive or robots.txt block: A
<meta name="robots" content="noindex">tag in the header alerts Google to disregard the page. Similarly, aDisallowrule in therobots.txtfile prevents the crawler from crawling the address. - Canonical Tag pointing to another address: If the
rel="canonical"tag indicates another URL as the main version, Google will transfer authority and will not index the current article.
The following table summarizes how these technical factors affect page presence:
| Failure stage | Symptom in Search Console | Likely cause | Recommended action |
|---|---|---|---|
| Crawling | Blocked by robots.txt file | Generic or incorrect Disallow rule | Adjust permissions in the application's robots.txt |
| Indexing | Excluded by 'noindex' tag | SEO plugin or CMS configured with a block | Remove the noindex meta tag from the affected page |
| Processing | Alternate page with proper canonical tag | URL points canonical to another page on the site | Review and fix the rel="canonical" tag in the header |
| Availability | Server error (5xx) | Hosting instability or code failure | Stabilize the server and check system logs |
The importance of internal link architecture and XML sitemaps
A poor internal linking structure reduces the crawler's ability to find and prioritize pages on a site. Orphan pages—those that do not receive any links from other internal pages—rarely receive attention from Googlebot.
Keeping an updated XML sitemap in Google Search Console ensures that new articles enter the discovery queue immediately after publication. However, the sitemap is only a suggestion: the search engine prioritizes pages backed by good internal link architecture. Ensuring that each new article receives contextual mentions from already established pages signals the thematic relevance of that content.
Content quality and usefulness in the indexing decision
Google discards pages that do not achieve a minimum level of originality and practical value for the user. Even if the page is technically perfect, the algorithm may choose not to index it if it evaluates the content as thin, redundant, or generated without commercial differentiation.
With updates focused on helpful content systems (Helpful Content), blog archives publishing commodity articles face the "Crawled - currently not indexed" status. To avoid this editorial rejection, content must directly answer search intent, present concrete data, and demonstrate authority on the subject. When analyzing the causes of an unindexed article, a lack of depth and the absence of Information Gain are often the hidden reasons.
Case study: indexing normalization in a B2B editorial collection
Companies with extensive archives frequently face traffic stagnation when dozens of published pages remain outside the index. A company in the B2B services sector noticed that 35% of its blog maintained the status of "Discovered - currently not indexed".
Upon performing the diagnosis, the team identified two central problems: lack of internal links and thin texts generated without contextual direction. By adopting the BlogPost Automático platform to restructure topic clusters and optimize articles with company-specific information, the indexing rate rose to 98% in six weeks, resulting in substantial organic growth without the need for daily manual rework.
How to use Google Search Console to identify the exact cause
The Page Indexing report in Google Search Console is the definitive tool to pinpoint the exact technical reason for a URL's absence. By pasting the complete link into the URL Inspection tool, the system shows the exact real-time diagnosis.
The two most frequent alerts in the report require distinct actions:
- Discovered - currently not indexed: Google knows the page exists, but hasn't had the crawl budget or priority interest to visit it yet. Solution: improve internal links pointing to it and submit the link via sitemap.
- Crawled - currently not indexed: Google visited and read the page, but decided not to store it in the index. Solution: rewrite the content adding unique value, fix the text structure, and ensure alignment with reader intent.
Frequently asked questions
How long does Google take to index a new article?
Indexing time varies from a few hours to a few weeks, depending on domain authority and publication frequency of the site. Established sites with an active sitemap usually have new pages indexed within 48 hours.
Why does Search Console show 'Crawled - currently not indexed'?
This status means that Googlebot visited the page, reading its content, but concluded that it does not add enough value to be included in the index. This usually happens due to thin content, duplicate text, or lack of thematic relevance within the site.
Does using AI in content production prevent Google indexing?
No, Google evaluates the quality, accuracy, and usefulness of content, regardless of how it was produced. The risk occurs when publishing generic, unreviewed automated content, which triggers filters against scaled content abuse.